AI chatbots need more books to learn from. These libraries are opening their stacks
Jun 12, 2025, 6:06 AM
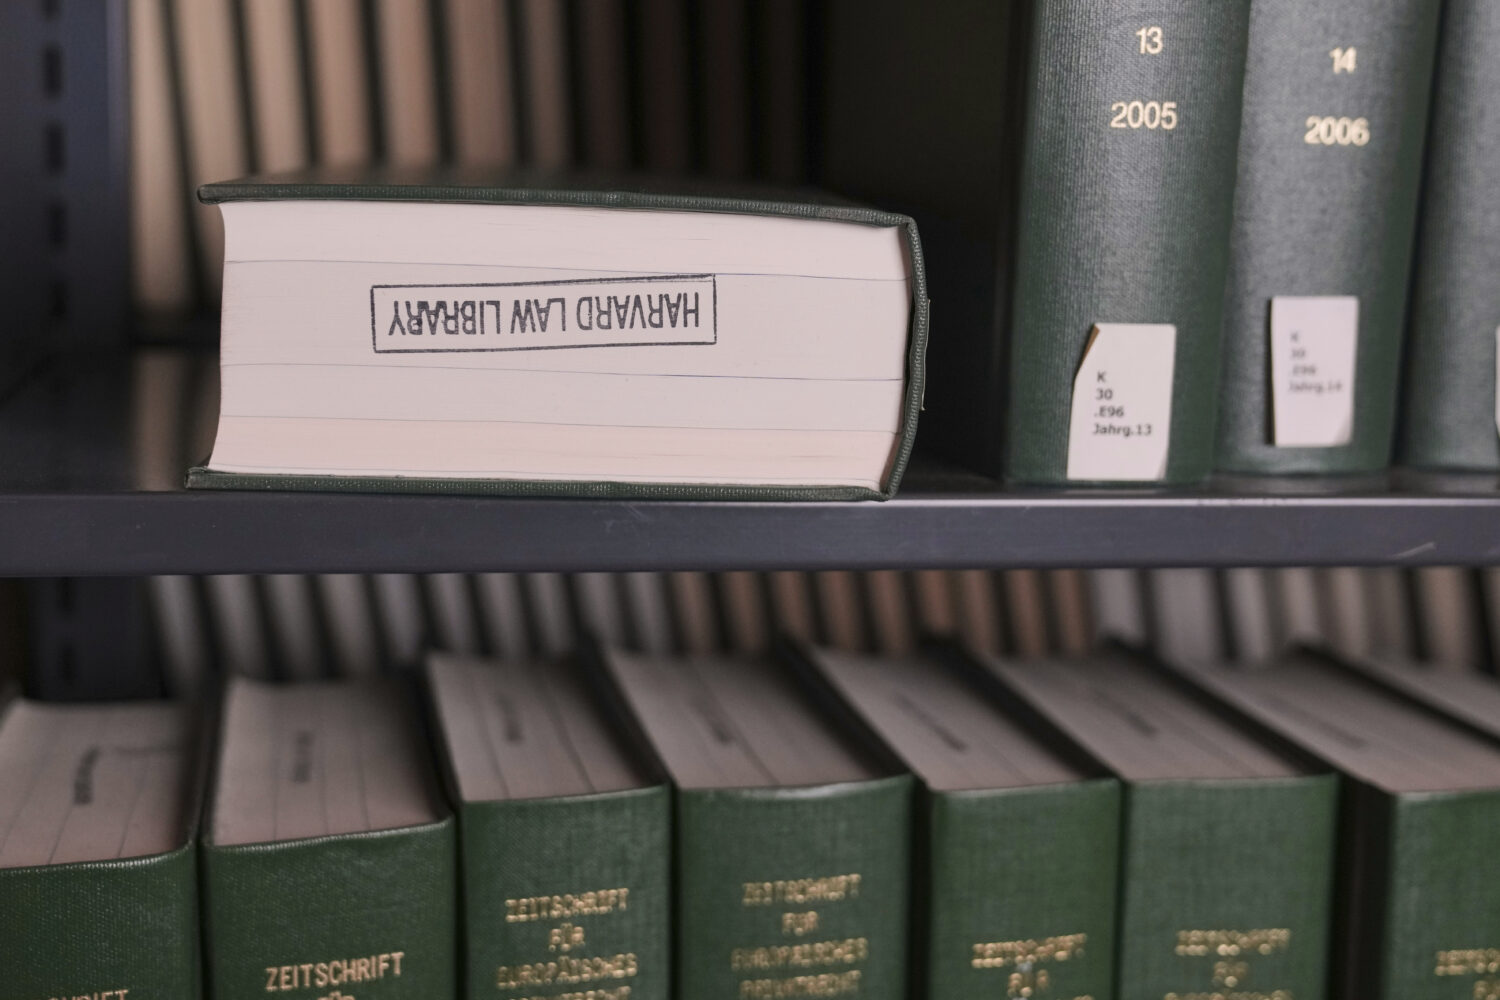
Books rest on a shelves at Langdell Hall, which houses the Harvard Law School library, Wednesday, Feb. 26, 2025, in Cambridge, Mass. (AP Photo/Charles Krupa)
Credit: ASSOCIATED PRESS
(AP Photo/Charles Krupa)

CAMBRIDGE, Mass. (AP) — Everything ever said on the internet was just the start of teaching artificial intelligence about humanity. Tech companies are now tapping into an older repository of knowledge: the library stacks.
Nearly one million books published as early as the 15th century — and in 254 languages — are part of a Harvard University collection being released to AI researchers Thursday. Also coming soon are troves of old newspapers and government documents held by Boston’s public library.
Cracking open the vaults to centuries-old tomes could be a data bonanza for tech companies battling lawsuits from living novelists, visual artistsand others whose creative works have been scooped up without their consent to train AI chatbots.
“It is a prudent decision to start with public domain data because that’s less controversial right now than content that’s still under copyright,” said Burton Davis, a deputy general counsel at Microsoft.
Davis said libraries also hold “significant amounts of interesting cultural, historical and language data” that’s missing from the past few decades of online commentary that AI chatbots have mostly learned from.
Supported by “unrestricted gifts” from Microsoft and ChatGPT maker OpenAI, the Harvard-based Institutional Data Initiative is working with libraries around the world on how to make their historic collections AI-ready in a way that also benefits libraries and the communities they serve.
“We’re trying to move some of the power from this current AI moment back to these institutions,” said Aristana Scourtas, who manages research at Harvard Law School’s Library Innovation Lab. “Librarians have always been the stewards of data and the stewards of information.”
Harvard’s newly released dataset, Institutional Books 1.0, contains more than 394 million scanned pages of paper. One of the earlier works is from the 1400s — a Korean painter’s handwritten thoughts about cultivating flowers and trees. The largest concentration of works is from the 19th century, on subjects such as literature, philosophy, law and agriculture, all of it meticulously preserved and organized by generations of librarians.
It promises to be a boon for AI developers trying to improve the accuracy and reliability of their systems.
“A lot of the data that’s been used in AI training has not come from original sources,” said the data initiative’s executive director, Greg Leppert, who is also chief technologist at Harvard’s Berkman Klein Center for Internet & Society. This book collection goes “all the way back to the physical copy that was scanned by the institutions that actually collected those items,” he said.
Before ChatGPT sparked a commercial AI frenzy, most AI researchers didn’t think much about the provenance of the passages of text they pulled from Wikipedia, from social media forums like Reddit and sometimes from deep repositories of pirated books. They just needed lots of what computer scientists call tokens — units of data, each of which can represent a piece of a word.
Harvard’s new AI training collection has an estimated 242 billion tokens, an amount that’s hard for humans to fathom but it’s still just a drop of what’s being fed into the most advanced AI systems. Facebook parent company Meta, for instance, has said the latest version of its AI large language model was trained on more than 30 trillion tokens pulled from text, images and videos.
Meta is also battling a lawsuit from comedian Sarah Silverman and other published authors who accuse the company of stealing their books from “shadow libraries” of pirated works.
Now, with some reservations, the real libraries are standing up.
OpenAI, which is also fighting a string of copyright lawsuits, donated $50 million this year to a group of research institutions including Oxford University’s 400-year-old Bodleian Library, which is digitizing rare texts and using AI to help transcribe them.
When the company first reached out to the Boston Public Library, one of the biggest in the U.S., the library made clear that any information it digitized would be for everyone, said Jessica Chapel, its chief of digital and online services.
“OpenAI had this interest in massive amounts of training data. We have an interest in massive amounts of digital objects. So this is kind of just a case that things are aligning,” Chapel said.
Digitization is expensive. It’s been painstaking work, for instance, for Boston’s library to scan and curate dozens of New England’s French-language newspapers that were widely read in the late 19th and early 20th century by Canadian immigrant communities from Quebec. Now that such text is of use as training data, it helps bankroll projects that librarians want to do anyway.
“We’ve been very clear that, ‘Hey, we’re a public library,’” Chapel said. “Our collections are held for public use, and anything we digitized as part of this project will be made public.”
Harvard’s collection was already digitized starting in 2006 for another tech giant, Google, in its controversial project to create a searchable online library of more than 20 million books.
Google spent years beating back legal challenges from authors to its online book library, which included many newer and copyrighted works. It was finally settled in 2016 when the U.S. Supreme Court let stand lower court rulings that rejected copyright infringement claims.
Now, for the first time, Google has worked with Harvard to retrieve public domain volumes from Google Books and clear the way for their release to AI developers. Copyright protections in the U.S. typically last for 95 years, and longer for sound recordings.
How useful all of this will be for the next generation of AI tools remains to be seen as the data gets shared Thursday on the Hugging Face platform, which hosts datasets and open-source AI models that anyone can download.
The book collection is more linguistically diverse than typical AI data sources. Fewer than half the volumes are in English, though European languages still dominate, particularly German, French, Italian, Spanish and Latin.
A book collection steeped in 19th century thought could also be “immensely critical” for the tech industry’s efforts to build AI agents that can plan and reason as well as humans, Leppert said.
“At a university, you have a lot of pedagogy around what it means to reason,” Leppert said. “You have a lot of scientific information about how to run processes and how to run analyses.”
At the same time, there’s also plenty of outdated data, from debunked scientific and medical theories to racist narratives.
“When you’re dealing with such a large data set, there are some tricky issues around harmful content and language,” said Kristi Mukk, a coordinator at Harvard’s Library Innovation Lab who said the initiative is trying to provide guidance about mitigating the risks of using the data, to “help them make their own informed decisions and use AI responsibly.”
————
The Associated Press and OpenAI have a licensing and technology agreement that allows OpenAI access to part of AP’s text archives.